Neuralinko
Mission-critical AI rack hardware optimized for massive model training, DeepSeek inference, and scalable enterprise cloud workloads.
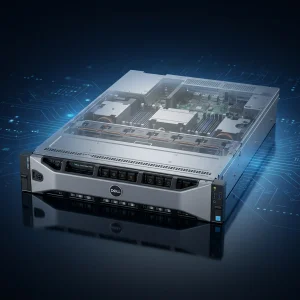
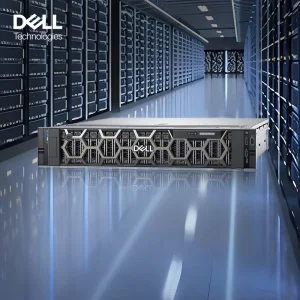
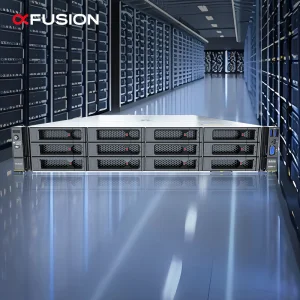
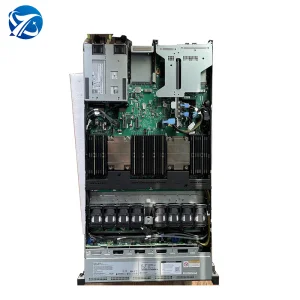
The global artificial intelligence hardware ecosystem is experiencing a seismic paradigm shift. As Foundation Models (FMs), Large Language Models (LLMs) such as DeepSeek, and real-time multimodal generative AI transition from experimental sandboxes to hyper-scale production deployments, standard enterprise computing platforms are no longer adequate. Hardware manufacturers are faced with the formidable task of co-designing compute, memory, interconnects, and cooling topographies to support ultra-dense compute operations.
This technical whitepaper provides an authoritative analysis of the Top 10 AI Application Verticals, the corresponding industrial hardware architectures required to sustain them, and a comprehensive teardown of enterprise OEM/ODM server manufacturing capabilities. Special focus is given to low-latency interconnects, PCIe 5.0/6.0 NVMe storage subsystems, liquid cooling infrastructures, and rack-scale energy efficiency optimization.
To maximize Return on Investment (ROI) and minimize Total Cost of Ownership (TCO), hardware deployments must match the precise mathematical and computational profile of the underlying AI software application. Below is an in-depth operational breakdown of the top 10 enterprise AI domains.
Workload Profile: High memory capacity, mass parallel processing, zero-latency prompt parsing.
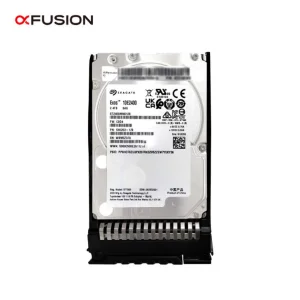
Hardware Blueprint: Dual-socket Intel Xeon / AMD EPYC processors coupled with multi-GPU backplanes (8x H100/A100 or optimized L40S arrays), paired with enterprise-grade NVMe PCIe SSDs (e.g., EP600 6.4TB) for ultra-fast model checkpoint loading and swap management.
Workload Profile: High-throughput computer vision analysis, synthetic dataset creation, sensor fusion telemetry.
Hardware Blueprint: 2U/4U high-density GPU nodes featuring robust PCI-e expansion risers, hot-swappable enterprise bays, and fault-tolerant redundant power supply units (80 PLUS Titanium 800W–2000W PSUs).
Workload Profile: 3D DICOM rendering, genomic sequence mapping, AI-assisted oncology diagnostics.
Hardware Blueprint: Dual-socket GPU workstations and rack servers equipped with enterprise RAM (DDR4/DDR5 ECC 256GB–1TB configurations) to prevent bit flips during micro-genomic calculations.
Workload Profile: Microsecond latency execution, complex statistical modeling, real-time risk assessment.
Hardware Blueprint: Short-depth 1U/2U optimized servers featuring high-frequency Intel Gold/Platinum CPUs, NVMe drive arrays with direct-attached PCIe lane architecture to minimize bus switching overhead.
Workload Profile: Edge visual quality inspection, automated defect recognition, predictive maintenance loops.
Hardware Blueprint: Thermally hardened short-depth industrial server chassis capable of operating in wide ambient temperature ranges with dust-filtered airflow and vibration isolation chassis mounts.
Workload Profile: Real-time NeRF rendering, generative video synthesis, virtual production background tracking.
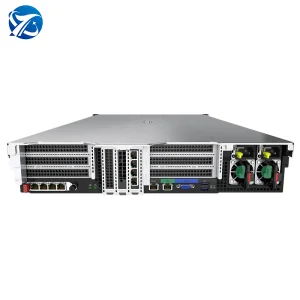
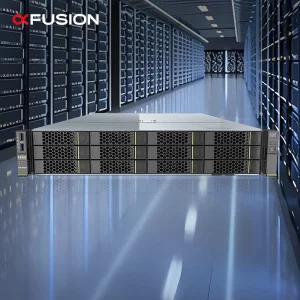
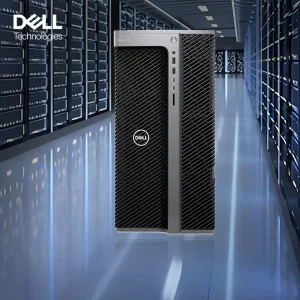
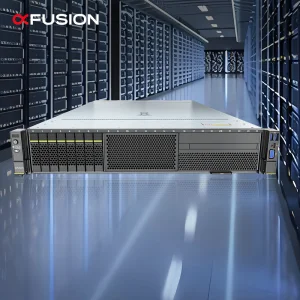
Hardware Blueprint: Multi-slot GPU compute platforms (e.g., Dell PowerEdge R960 series or xFusion 2288H V7) supporting multi-channel PCIe 5.0 expansion cards and enterprise storage arrays.
Workload Profile: Network packet telemetry processing, anomaly detection using deep neural networks.
Hardware Blueprint: Network-attached storage (NAS) integrated server nodes with quad-port 10GbE/25GbE/100GbE SmartNICs and hardware acceleration modules.
Workload Profile: Dynamic virtualization, containerized microservices orchestration (Kubernetes/Docker).
Hardware Blueprint: Standardized 1U/2U rack servers (such as PowerEdge R650 or FusionServer 1288H V7) providing hyper-scalable CPU-to-RAM mapping and IPMI 2.0 remote management capabilities.
Workload Profile: Climate modeling, molecular dynamics simulations, quantum algorithm emulation.
Hardware Blueprint: Direct-to-chip liquid-cooled server racks supporting liquid-to-liquid heat exchangers and high-speed InfiniBand interconnect backplanes.
Workload Profile: Real-time automatic speech recognition (ASR) and text-to-speech (TTS) stream processing.
Hardware Blueprint: Dense inference servers with low-power high-throughput GPU accelerators optimized for linear matrix operations.
As a leading hardware engineering firm in the global AI ecosystem, Neuralinko Intelligent Technology Co., Ltd. stands at the forefront of high-performance GPU server design, AI compute infrastructure, and bespoke data center integration.
Established in 2018, Neuralinko operates from a state-of-the-art 386㎡ production and engineering facility. Backed by over 8 years of deep industry expertise and 6 years of global export specialization, the company generates an annual export revenue exceeding USD 18 million across North America, Europe, Southeast Asia, the Middle East, and Australia.
Neuralinko maintains strong long-term strategic partnerships with over 1,200 global supply chain vendors. This expansive ecosystem ensures stable silicon component allocations, competitive pricing metrics, and rapid order fulfillment lead times.
Driven by an elite R&D group of 118 specialized engineers, Neuralinko introduced 126 new system configurations and product SKUs in the past year alone. Key enterprise services include customized chassis engineering, tailored GPU motherboard backplanes, BIOS/firmware optimization, private labeling, and rack-level turnkey deployment solutions.
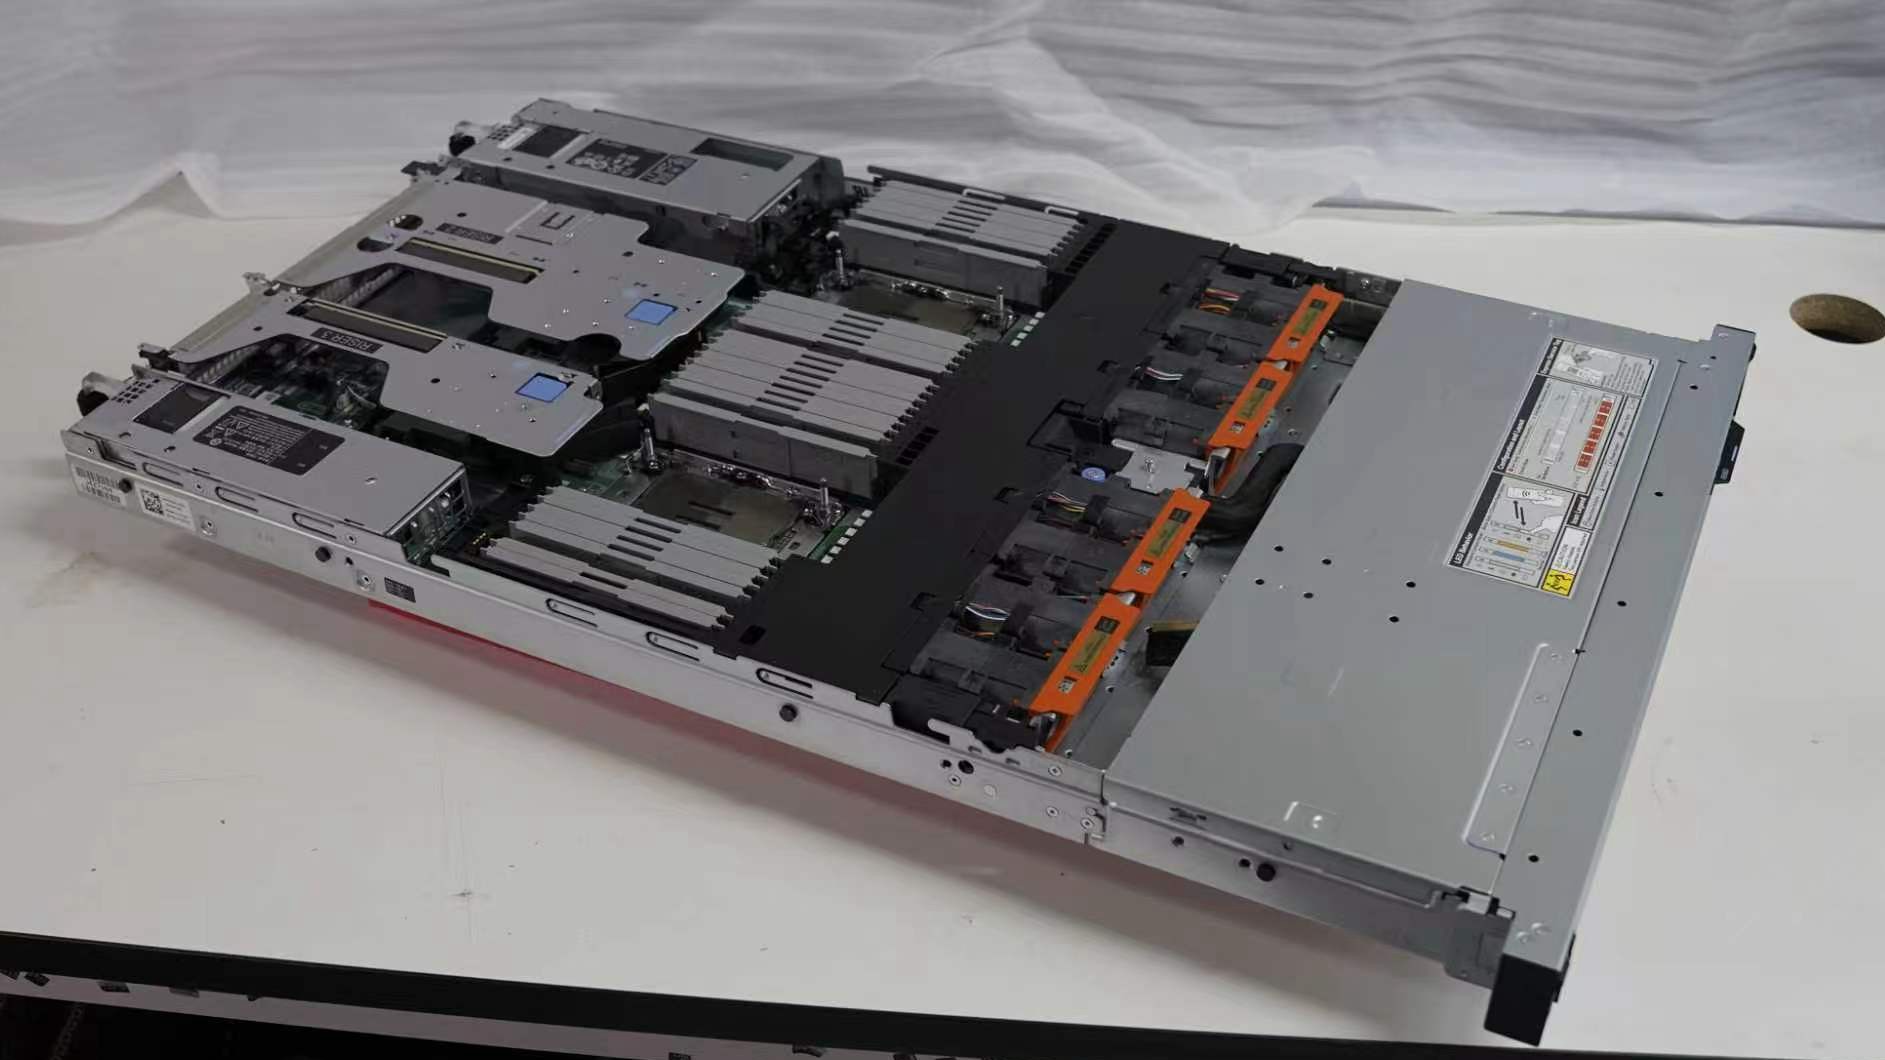
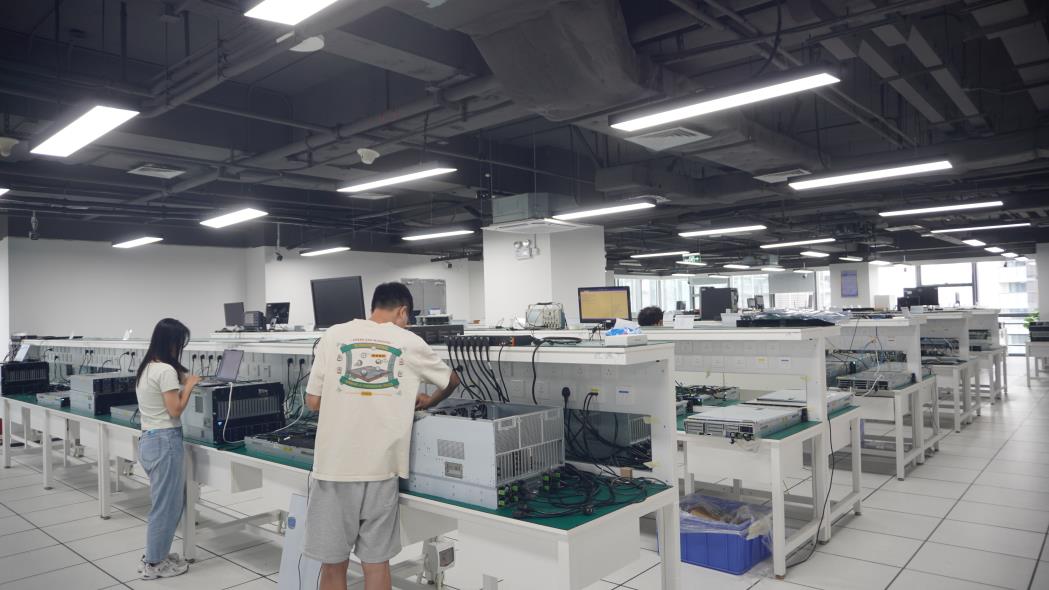
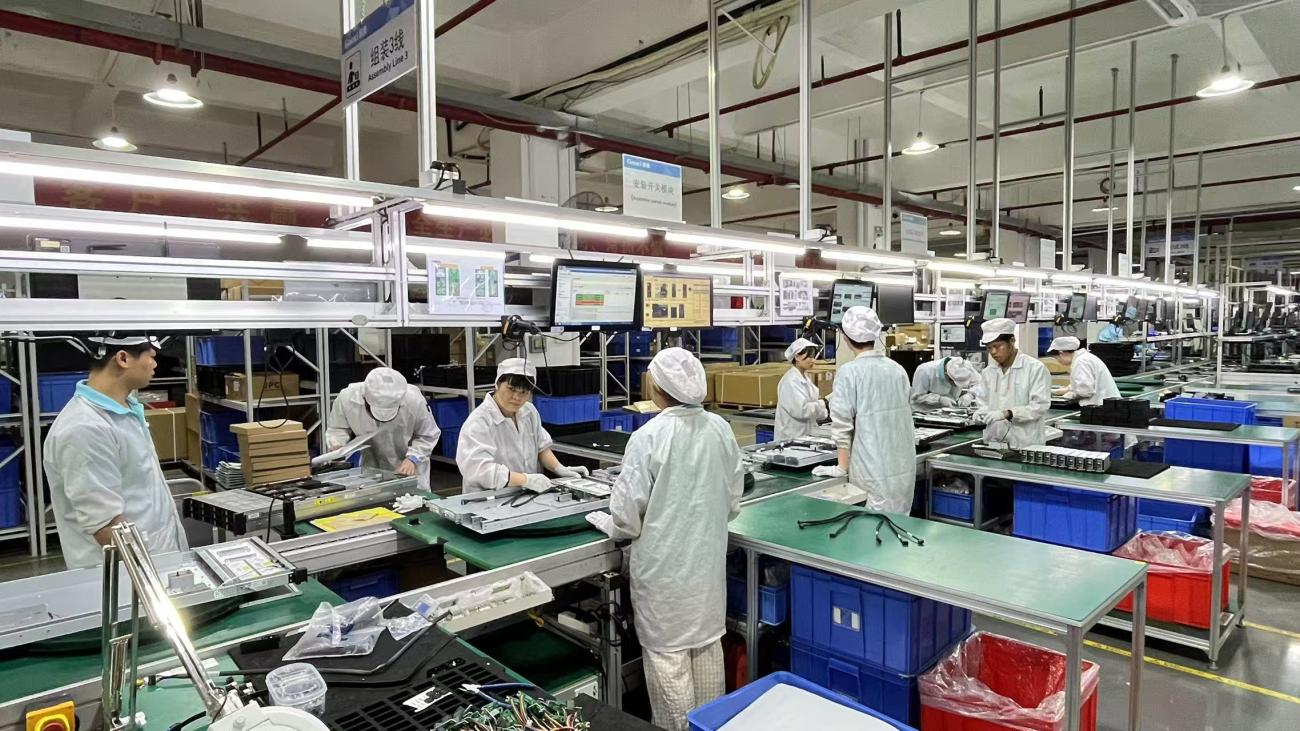
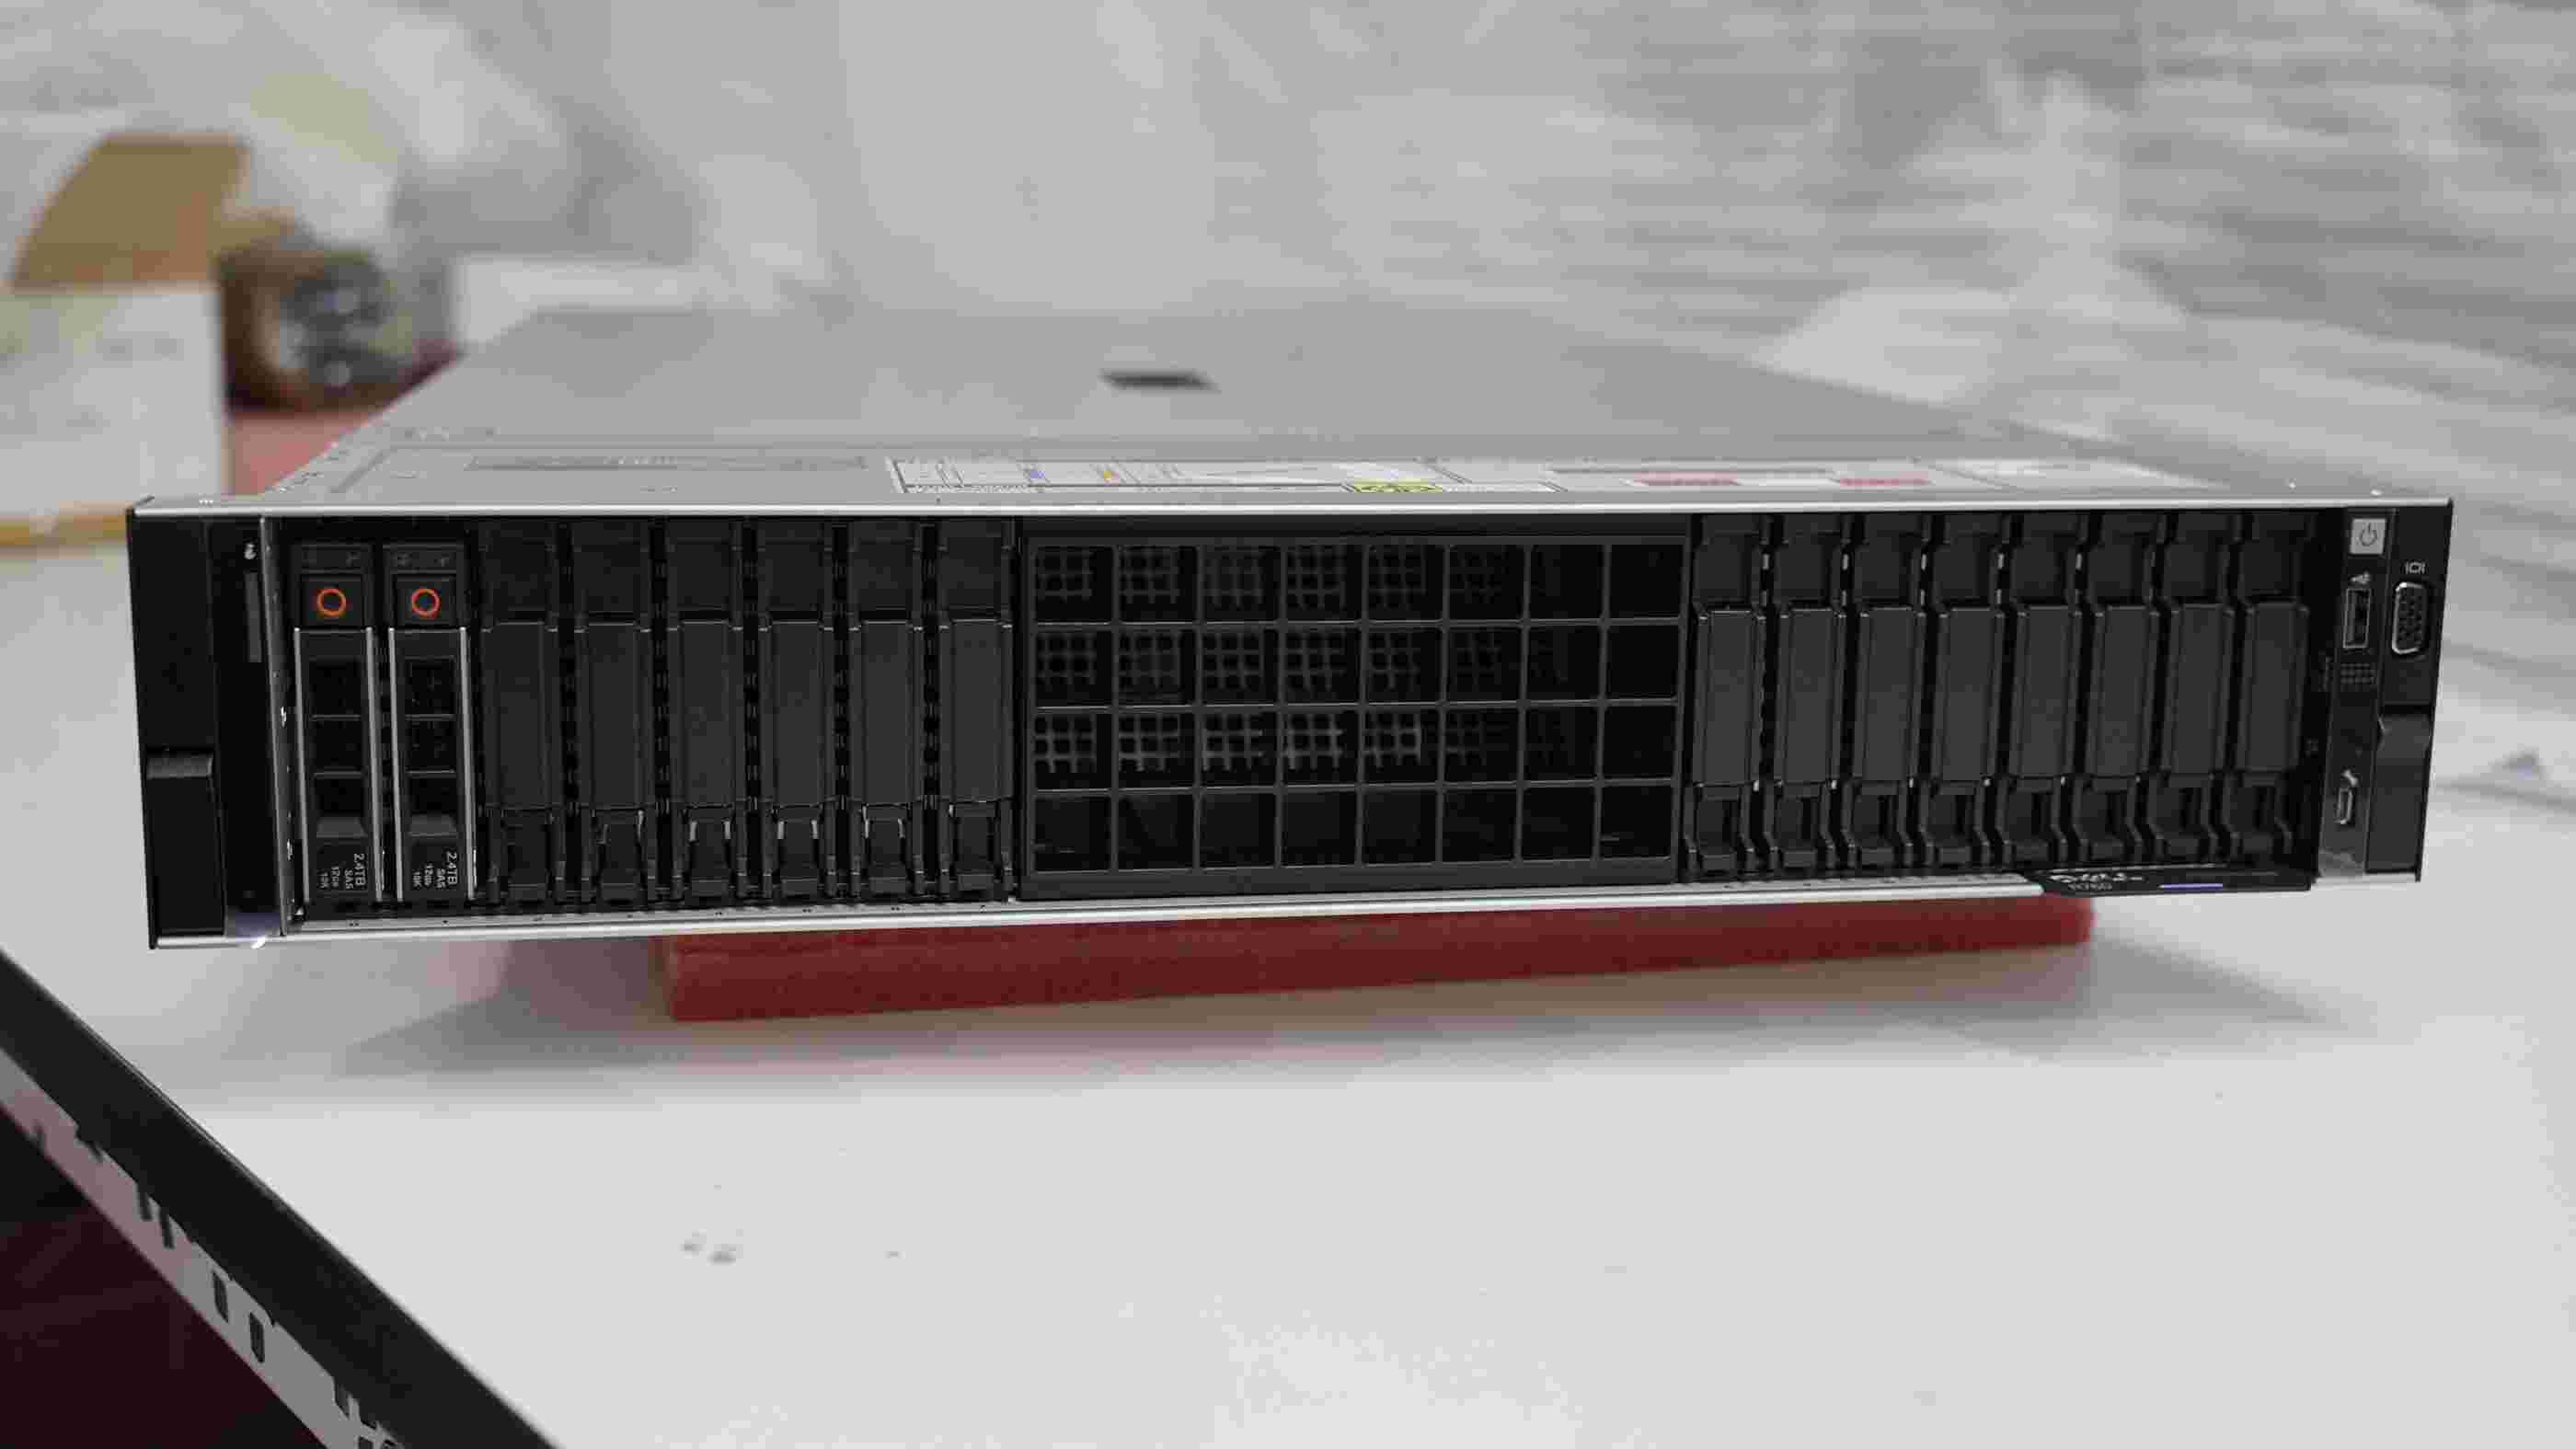
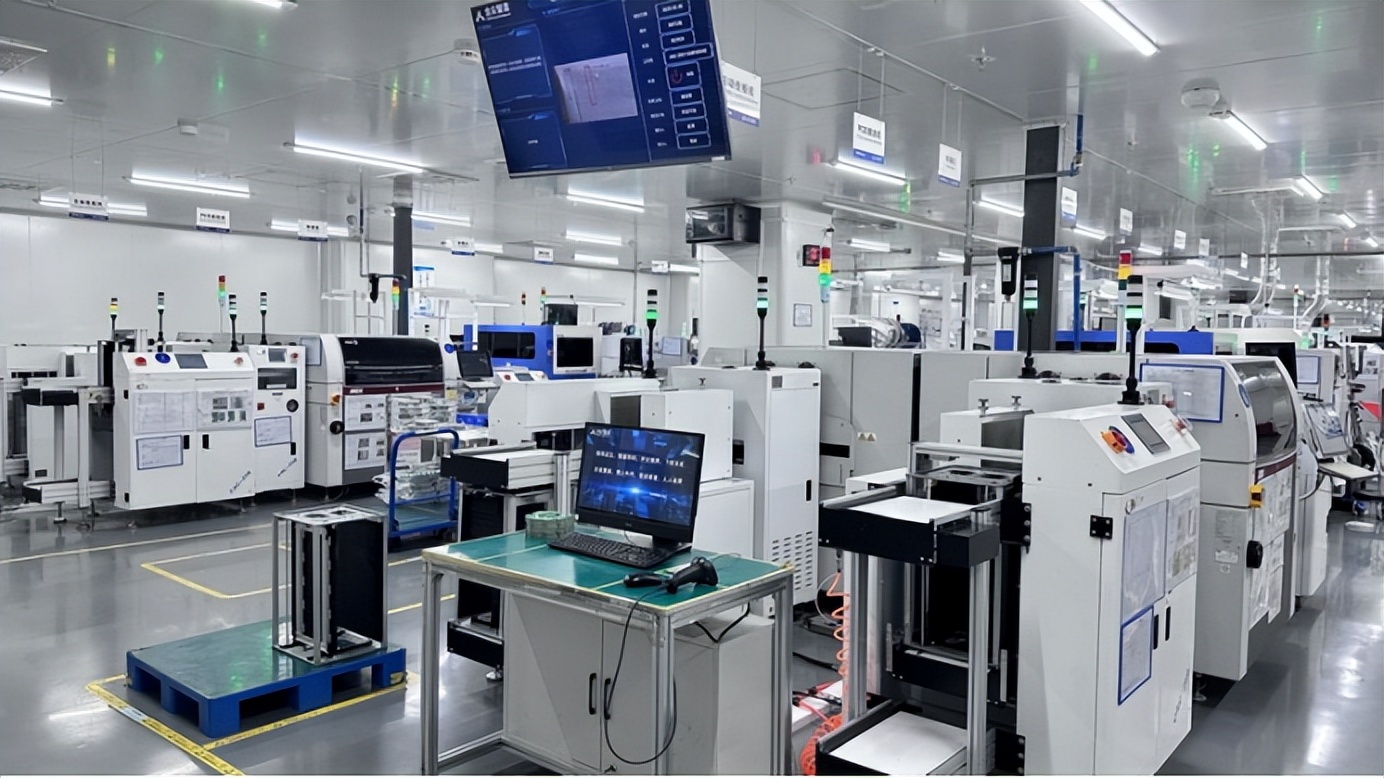
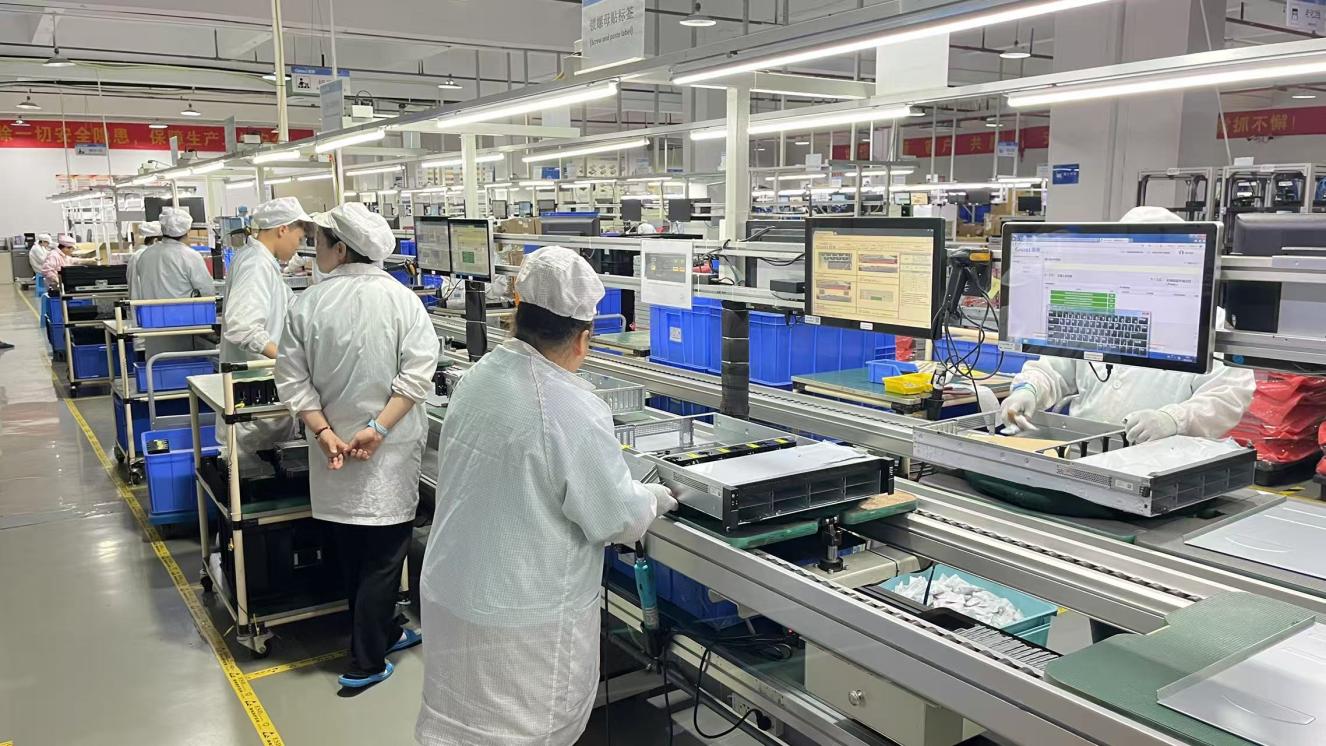
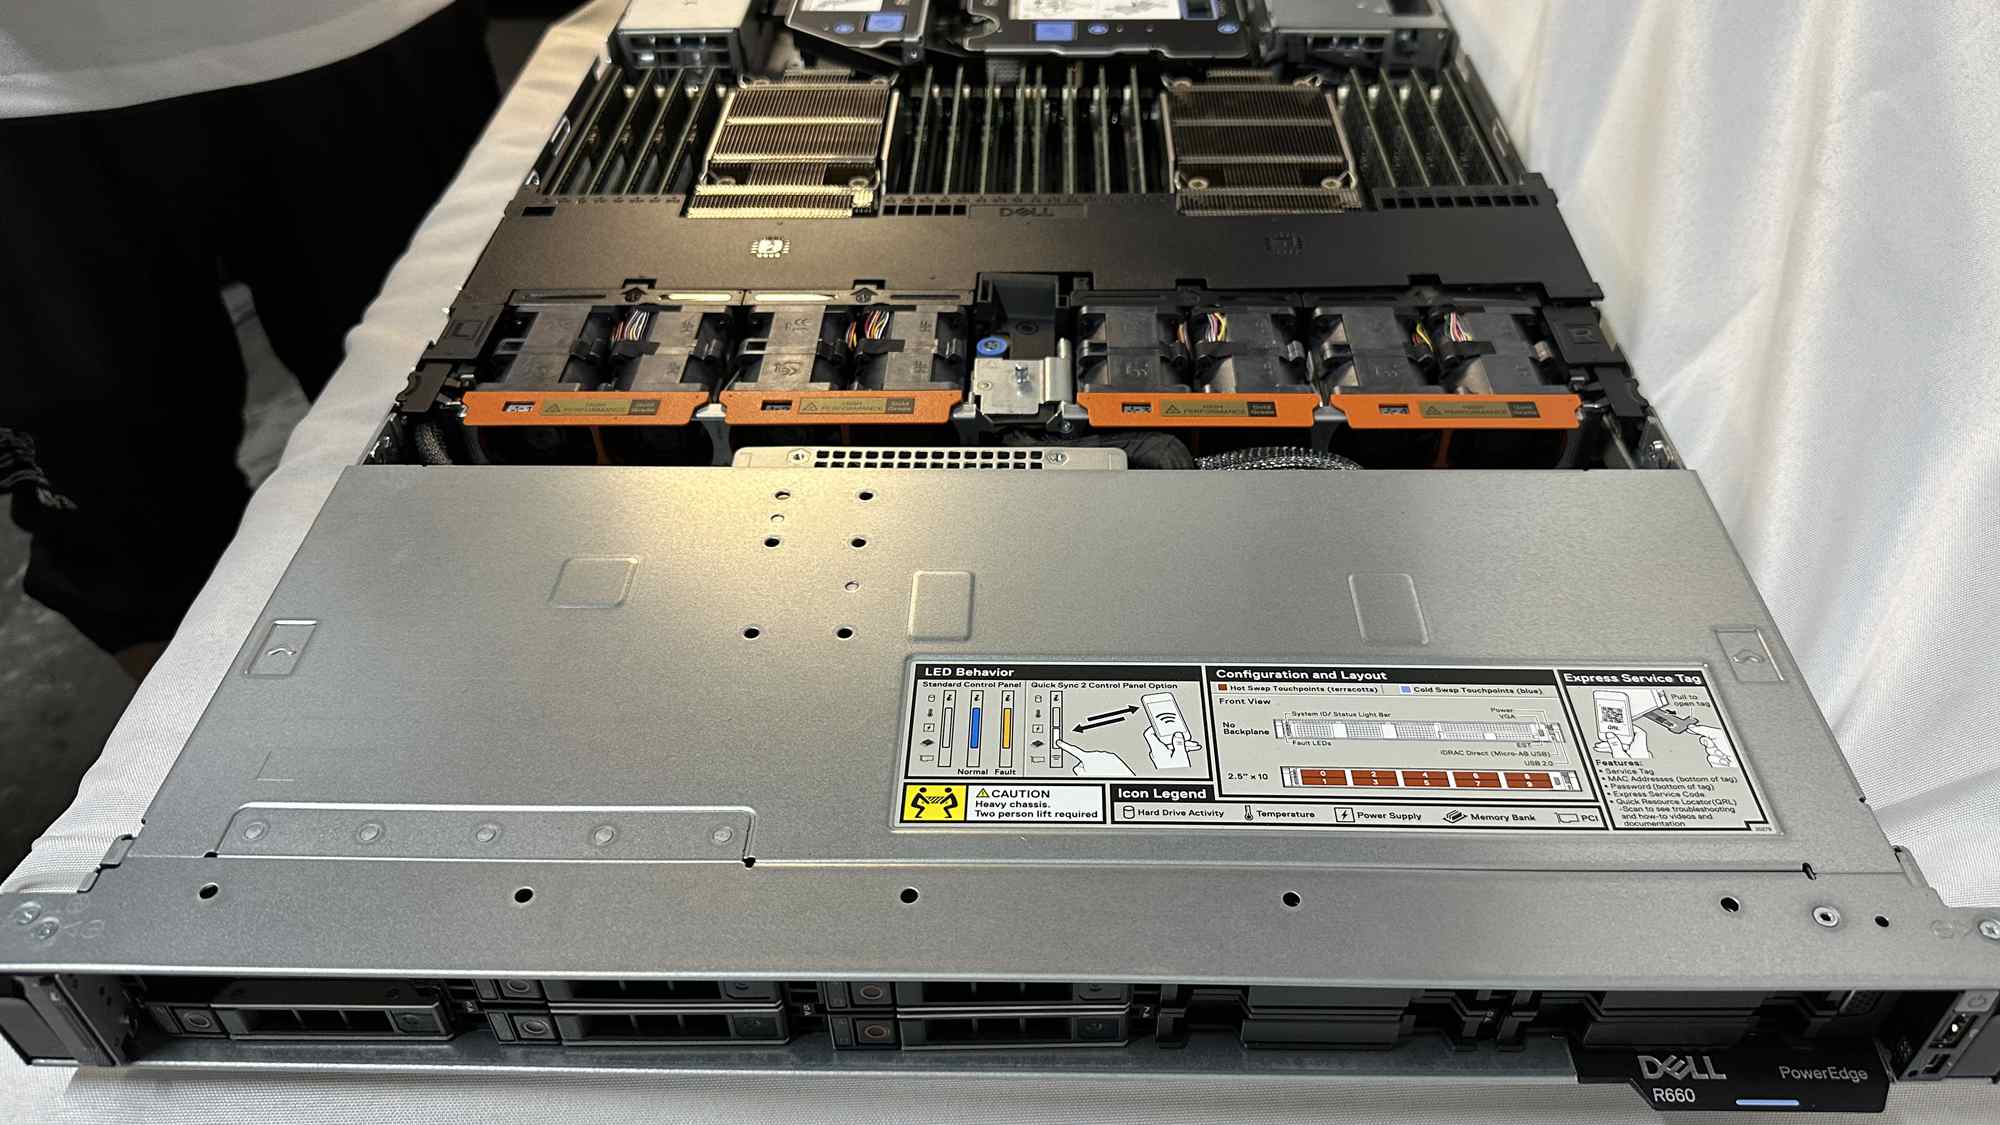
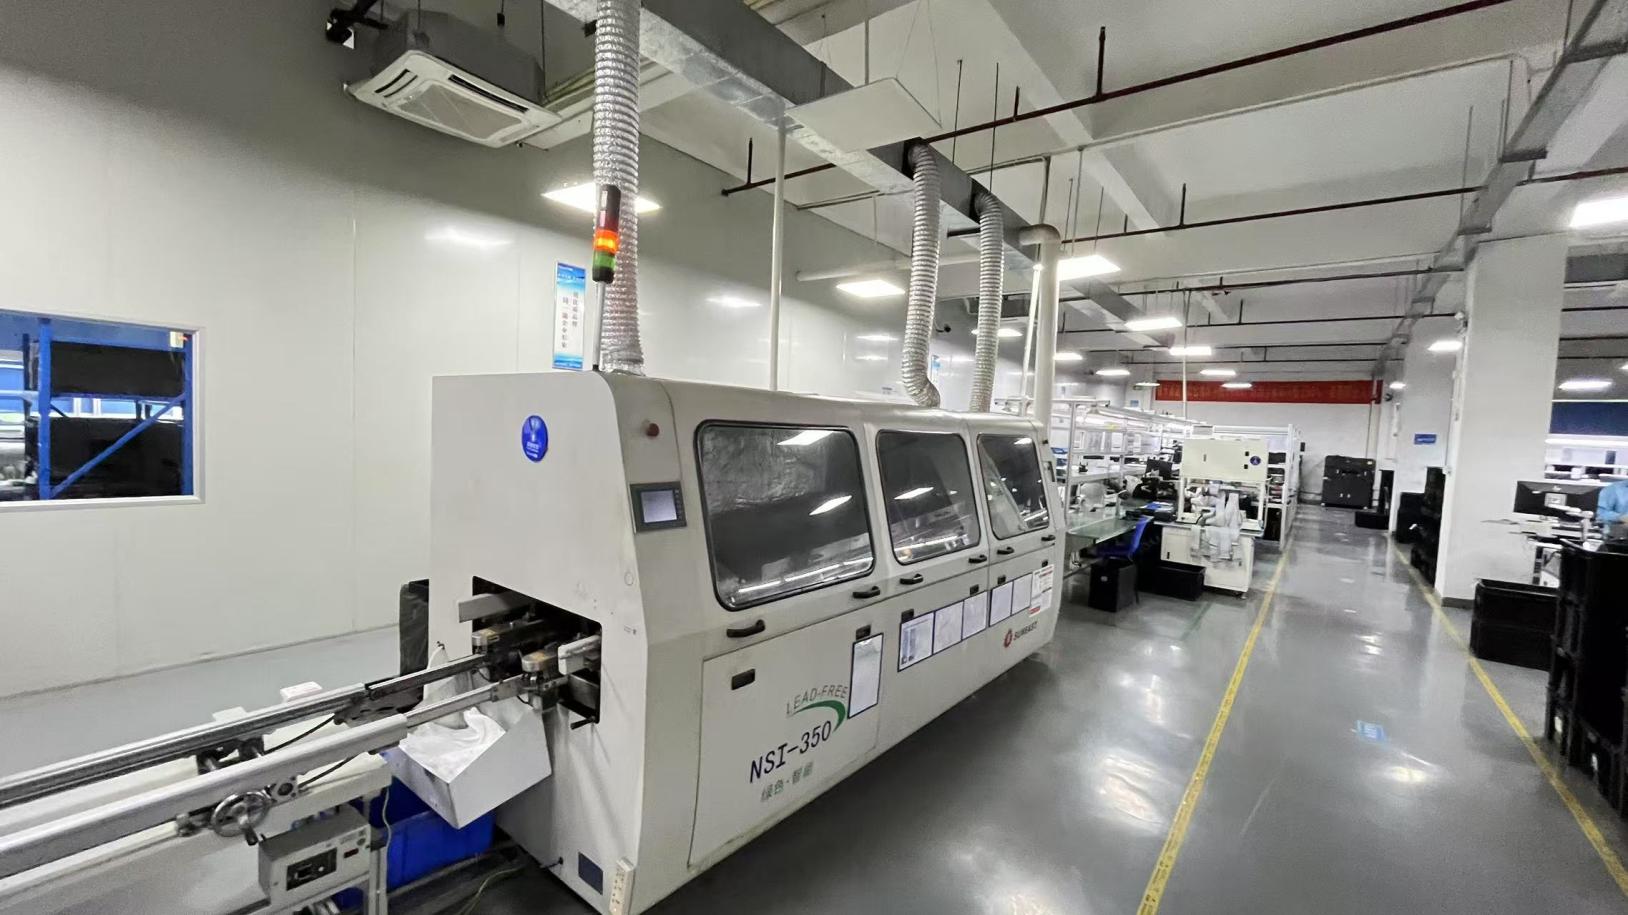
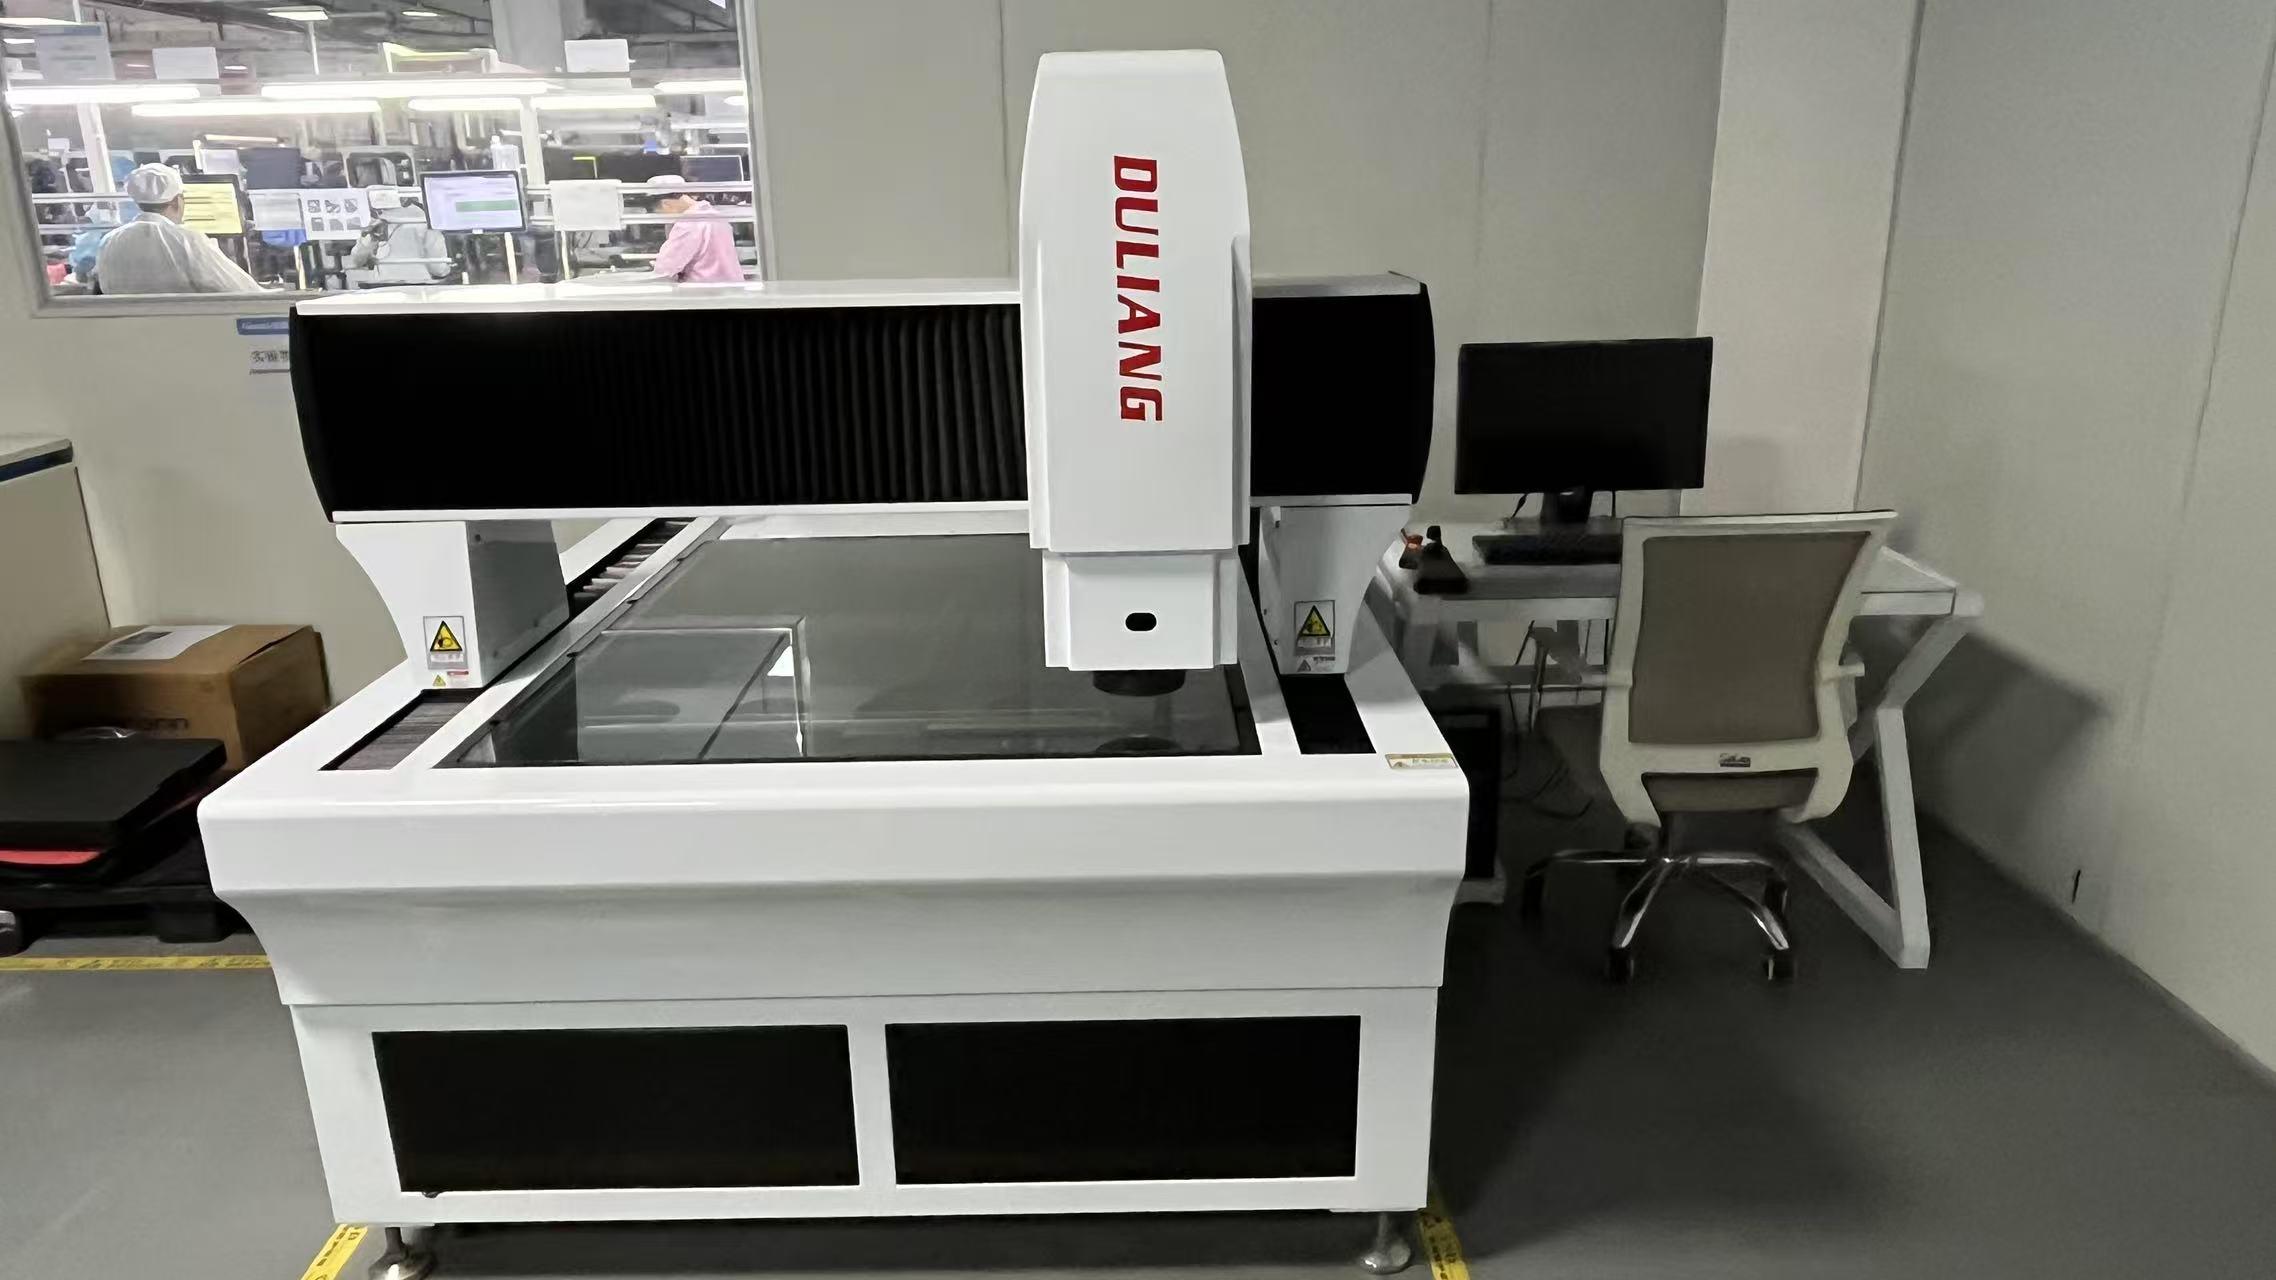
Visual verification of Neuralinko's cleanroom production, server burn-in racks, and advanced quality inspection bays:
As deep neural networks continue to expand exponentially in parameters, server architectural design is shifting from standard motherboard layouts to hyper-converged, low-latency topology models.
| Architectural Era | Interconnect Technology | Storage Standard | Thermal Dissipation | Target Workload Efficiency |
|---|---|---|---|---|
| Gen-4 Legacy (2020-2022) | PCIe 4.0 x16 / 100G InfiniBand | SATA / SAS / PCIe 3.0 NVMe | Standard Forced Air Cooling | CNN / Basic NLP Inference |
| Gen-5 Current (2023-2025) | PCIe 5.0 / NVLink 4.0 / 400G RoCEv2 | PCIe 5.0 EP600 NVMe SSDs | Hybrid Air & Cold Plate Liquid | LLM Fine-Tuning / DeepSeek 70B+ |
| Gen-6 Future (2026+) | PCIe 6.0 PAM4 / CXL 3.0 Memory Pool | PCIe 6.0 NVMe-oF Flash Fabrics | Full Immersion Cooling (PUE < 1.15) | Trillion-Parameter FM Multimodal Clusters |
Explore our complete inventory of enterprise rack hardware, workstation servers, and high-speed memory extensions.