Neuralinko
Choosing a machine learning server manufacturer is no longer a simple hardware comparison. It is an infrastructure decision involving performance, energy, reliability, and future expansion.
The market is moving quickly. IDC reported that global spending on AI infrastructure was forecast to reach $154 billion in 2024, representing 44% annual growth. Stanford University’s AI Index 2024 also recorded $25.2 billion in global private investment in generative AI during 2023. These figures show why organizations are evaluating GPU servers, high-speed networking, liquid cooling, and technical support more carefully.
Lisa Su, AMD’s chair and chief executive, described AI as “the most important mega trend in all of technology” during her CES 2024 keynote. Her statement reflects a practical reality: server choices now influence model-training speed, operating costs, and product delivery schedules.
Specifications alone are not enough. A server may list powerful accelerators, yet still struggle with memory bandwidth, heat removal, or software compatibility. Small details matter. Check rack depth, power connectors, warranty response times, and replacement-part availability. Ask whether the manufacturer has tested your preferred frameworks and datasets.
Experience matters here.
A useful evaluation should compare benchmark results with real workloads, not marketing claims. It should also examine three-year operating costs, including electricity and maintenance. That calculation is often overlooked.
No manufacturer is perfect. Even strong suppliers may have inconsistent delivery times or limited regional support. That uncertainty deserves honest discussion. This guide explains how to assess a machine learning server manufacturer through measurable performance, verified references, engineering expertise, and dependable after-sales service.
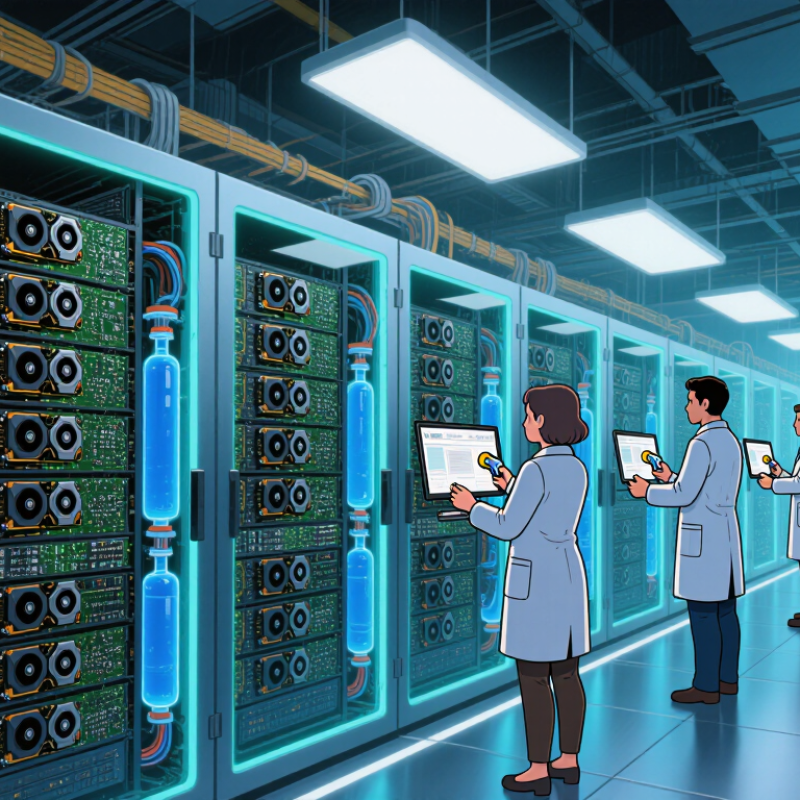
Choosing a machine learning server manufacturer starts with the workload, not glossy hardware claims. Training servers need strong accelerator performance, fast interconnects, and high-capacity memory. These resources shorten repeated model runs and reduce waiting between experiments. Inference servers face different pressures. They must deliver stable latency, predictable throughput, and efficient power use. A server handling live image requests may need low response times, while batch scoring can prioritize total requests per hour. That difference matters.
MLPerf Time-to-Accuracy offers a practical way to compare training performance. It measures how quickly a system reaches a defined model quality target. Ask whether the tested model, dataset, software version, and optimization settings match your project. Otherwise, a strong benchmark result may mislead your purchasing team. Use results as evidence, not prophecy. Also inspect MLPerf Inference results for latency, throughput, and power behavior under realistic batch sizes. Tiny batch tests can look impressive but fail under production traffic.
During vendor evaluations, request a small proof-of-concept using your own data pipeline. Measure checkpoint time, failed-job recovery, cooling noise, and support response. I once focused too heavily on accelerator speed and underestimated storage delays. That mistake made training feel slower than expected. It still influences my evaluation process. Reliable manufacturers explain limitations, publish repeatable test conditions, and provide clear maintenance procedures. Look beyond peak numbers. A dependable server should fit your team’s skills, deployment schedule, and tolerance for operational surprises.
Identify whether you need training, live inference, or batch scoring. Training needs accelerator power, fast interconnects, and large memory. Live inference needs stable latency. Batch scoring may prioritize requests per hour. Write down expected traffic, model size, and response targets. Details matter.
Check how quickly the system reaches a defined model quality target. Compare the tested model, dataset, software, and optimization settings with your project. Different conditions can produce misleading results. Treat benchmark numbers as evidence, not certainty.
Small batches may show excellent latency. Production traffic can behave differently. Test live requests and larger batches when appropriate. Measure latency, throughput, and power use together. A fast demo may disappoint later.
Use your own data pipeline and model. Measure checkpoint time, storage delays, failed-job recovery, cooling noise, and support response. Test for several hours, not ten minutes. Short tests can hide thermal throttling. I once underestimated storage delays. That mistake changed my evaluation process.
Calculate accelerator, processor, memory, storage, and fan consumption together. Leave at least 20 percent power headroom. A multi-accelerator server can exceed 2,800 watts. Confirm airflow direction, ambient temperature, and thermal logs. Room fans are not enough.
Ask about continuous power ratings, redundancy, voltage options, and connector quality. Check for front-to-back airflow and replaceable fans. Liquid cooling can increase density. It also adds pumps, tubing, and maintenance tasks. Request clear service procedures and acoustic readings.
Include purchase price, electricity, cooling, software support, replacement parts, installation, and firmware updates. Request a five-year estimate using realistic utilization. Check rack rails and deployment labor. A cheaper invoice may create higher operating costs.
Confirm coverage length, replacement procedures, labor costs, and excluded parts. Ask whether critical components can arrive within one business day. Define response, diagnosis, and repair targets. Request escalation contacts and service reports. Vague promises deserve another review.
Certification can indicate structured security management. It does not prove every process works well. Verify certificate scope, validity, facilities, access controls, incident response, and supplier management. Ask for documented evidence. Do not rely on a logo alone.
Choosing the right machine learning server manufacturer begins with a clear understanding of your workload. Separate model training from inference requirements, and use time-to-accuracy measurements, such as those reflected in MLPerf benchmarks, to assess practical performance rather than relying only on theoretical specifications. For demanding workloads, compare accelerator capacity carefully, including 80GB of HBM3 memory and bandwidth of up to 3.35TB/s, while also confirming that the system can scale efficiently through PCIe 5.0 x16, which delivers approximately 64GB/s in each direction.
Power, cooling, and long-term operating costs are equally important. High-performance SXM accelerators may reach a 700W TDP, so the server must provide suitable airflow, power delivery, and thermal management. Finally, evaluate each machine learning server manufacturer according to total cost of ownership, warranty coverage, ISO 27001 certification, replacement policies, and support SLAs. A reliable supplier should offer transparent pricing, scalable configurations, and responsive technical assistance that supports both current projects and future growth.